
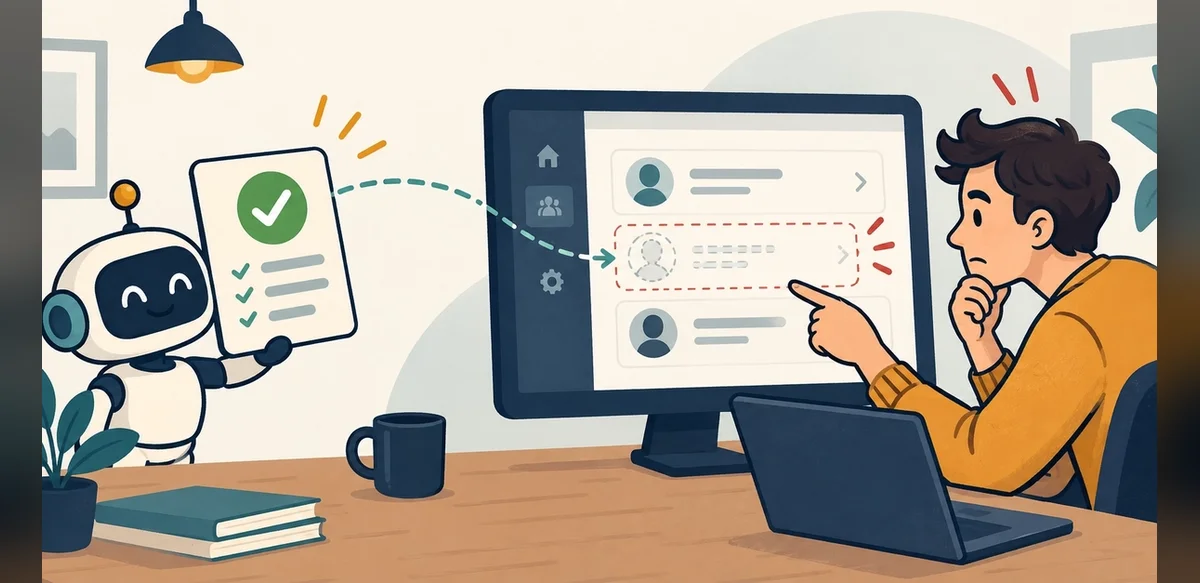
Artificial intelligence systems designed for software testing often increase the overall volume of test cases executed during development cycles. However, these systems frequently overlook specific defects that carry significant consequences for application reliability and user experience. Developers report that while automated generation expands coverage metrics, critical issues in edge cases or complex interactions remain undetected until manual review or live deployment.
The core challenge arises from the way AI models prioritize patterns observed in training data. Generated tests tend to focus on common scenarios derived from historical code repositories. This approach leaves gaps when software involves novel architectures or unusual data flows not represented in prior examples. As a result, teams may achieve high percentage scores on coverage reports yet encounter failures in production environments.
Industry observers note that integration of machine learning into testing frameworks requires careful calibration. Overreliance on automated outputs can create a false sense of security among engineering groups. Experts recommend combining AI assistance with targeted human oversight to address scenarios where statistical predictions fall short. Such hybrid methods help maintain balance between efficiency gains and thorough validation.
Further analysis shows that AI-generated tests excel at repetitive checks but struggle with contextual understanding of business logic. For instance, a financial application might pass numerous unit tests while missing vulnerabilities related to regulatory compliance under rare transaction volumes. These oversights highlight the need for supplementary strategies that incorporate domain-specific knowledge beyond algorithmic generation.
Organizations adopting these technologies continue to refine their processes. Feedback loops between testers and AI tools allow incremental improvements over successive project iterations. Nevertheless, the fundamental limitation persists: automated systems optimize for measurable outputs rather than exhaustive exploration of potential failure modes. Continued research into explainable AI may eventually narrow this divide, yet current implementations demand cautious application alongside traditional verification techniques.
In summary, the expansion of test coverage through artificial intelligence does not guarantee identification of every relevant defect. Teams benefit from recognizing these constraints and structuring workflows that leverage both computational speed and human judgment. This balanced perspective supports more robust software outcomes across diverse development contexts.